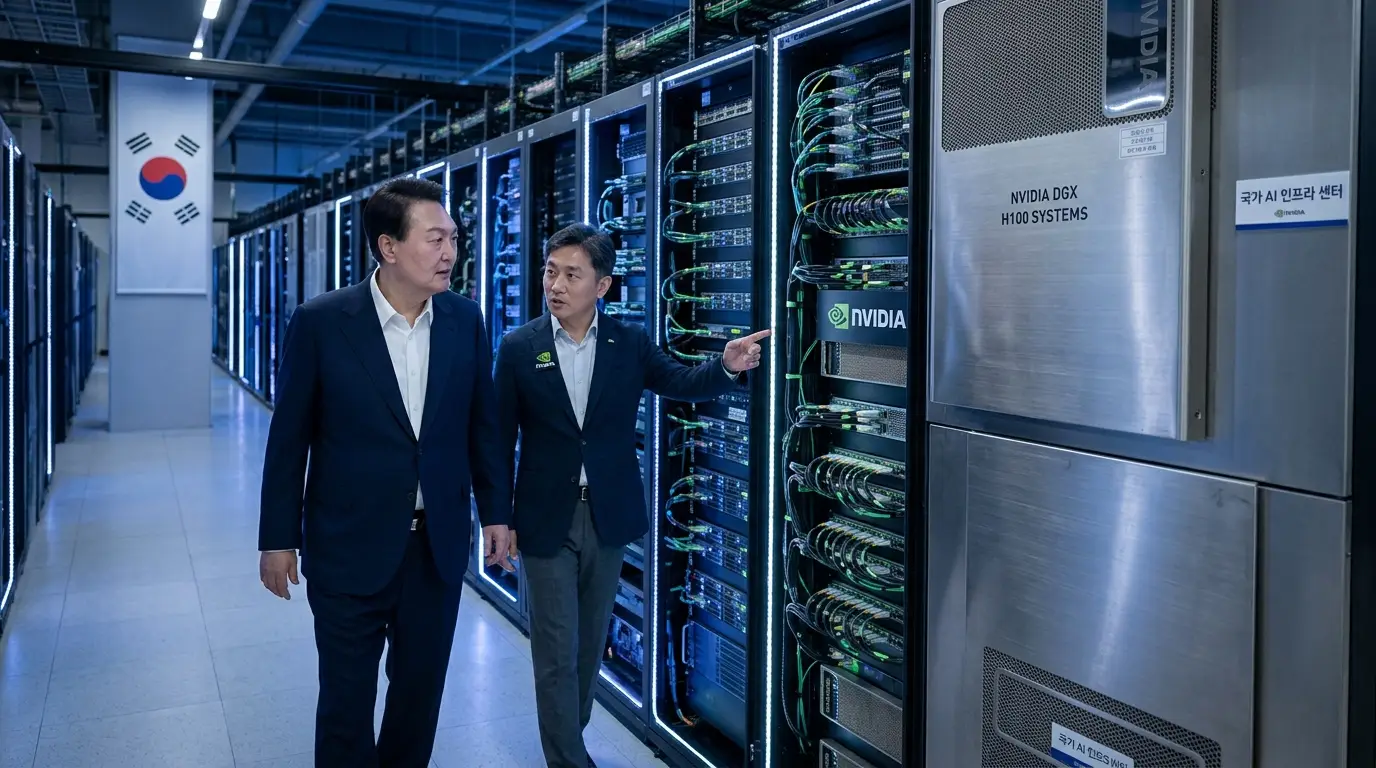
National governments are waking up to a harsh reality: relying entirely on foreign cloud giants for artificial intelligence compute is a massive strategic vulnerability. South Korea is actively fighting this trend by locking in a massive infrastructure pact. In a major push to secure digital independence, the country is rapidly expanding its sovereign AI collaboration with NVIDIA to build a completely domestic tech stack. This sprawling initiative covers everything from next-generation silicon design to foundation model security, ensuring that Korean data stays on Korean soil while still tapping into world-class compute power.
Forging A Hybrid Silicon Backbone
The most critical piece of this puzzle sits at the hardware level. You cannot run a sovereign AI ecosystem if you cannot connect your local chips to the broader global architecture. To solve this, the South Korean Ministry of Science and ICT is working directly with NVIDIA to integrate domestic Neural Processing Units (NPUs) and custom accelerators into the broader rack-scale ecosystem. This is where NVIDIA NVLink Fusion enters the chat. By adopting this high-bandwidth interconnect technology, local chipmakers can seamlessly plug their custom silicon into global-standard AI factories without rebuilding their entire networking stack.
This hybrid approach is already yielding real-world partnerships. Major telecommunications giant SK Telecom is teaming up with local AI chip startup Rebellions to deploy these custom architectures directly into national data centers. Instead of just buying off-the-shelf hardware, they are building a localized compute grid that supports heavy domestic workloads while maintaining the throughput required for modern generative tasks.
| National Compute Metric | Current Benchmark Target | Primary Hardware Architecture | Expected Deployment Window |
| K-Cloud Grid Capacity | 100,000+ Enterprise Accelerators | Hybrid Rack-Scale Interconnects | Active Rollout |
| Domestic NPU Integration | 3 Major Local Silicon Fabs | Custom ASIC + XPU Bridges | Testing & QA |
| Sovereign LLM Inference | Sub-50ms Latency Nationwide | Distributed Open-Source Runtimes | Beta Integration |
Solving The Inference Bottleneck
Hardware is only half the battle; running the actual models efficiently is where most enterprise deployments choke. Through the national AI for All initiative, the government is funding three major consortia and four leading local foundation model builders to optimize how they serve intelligence to end users. They are deploying NVIDIA Dynamo, an open-source distributed inference framework, to handle the heavy lifting.
By standardizing on this specific software layer, Korean developers can scale their models across multi-node environments without getting locked into proprietary black boxes. It essentially acts as the orchestration layer above the raw compute, ensuring that when millions of citizens query a domestic language model simultaneously, the system doesn't collapse under the latency.
The End Of The Walled Garden
What makes this collaboration so fascinating is the shift away from pure vendor lock-in. By blending global interconnect standards with domestic silicon and open-source inference software, South Korea is engineering a middle path. They get the blistering performance of top-tier global infrastructure without sacrificing control over their intellectual property or citizen data. For other nations watching closely, this blueprint proves that you do not have to choose between technological sovereignty and raw processing power. You just need to architect the bridge correctly.
Popular news
Singapore General Hospital Wins Global Healthcare Award For Antibiotic AI Tool
Nvidia CEO Jensen Huang Admits to an Affair as Company Probes Possible Chinese Espionage
Global Media Leaders Forge AI Action Plan at Beijing Summit
Developers Test Free Local AI Stack Against Premium Cloud Coding Agents
Valve Updates Steam Release Rules to Manage AI Game Surge