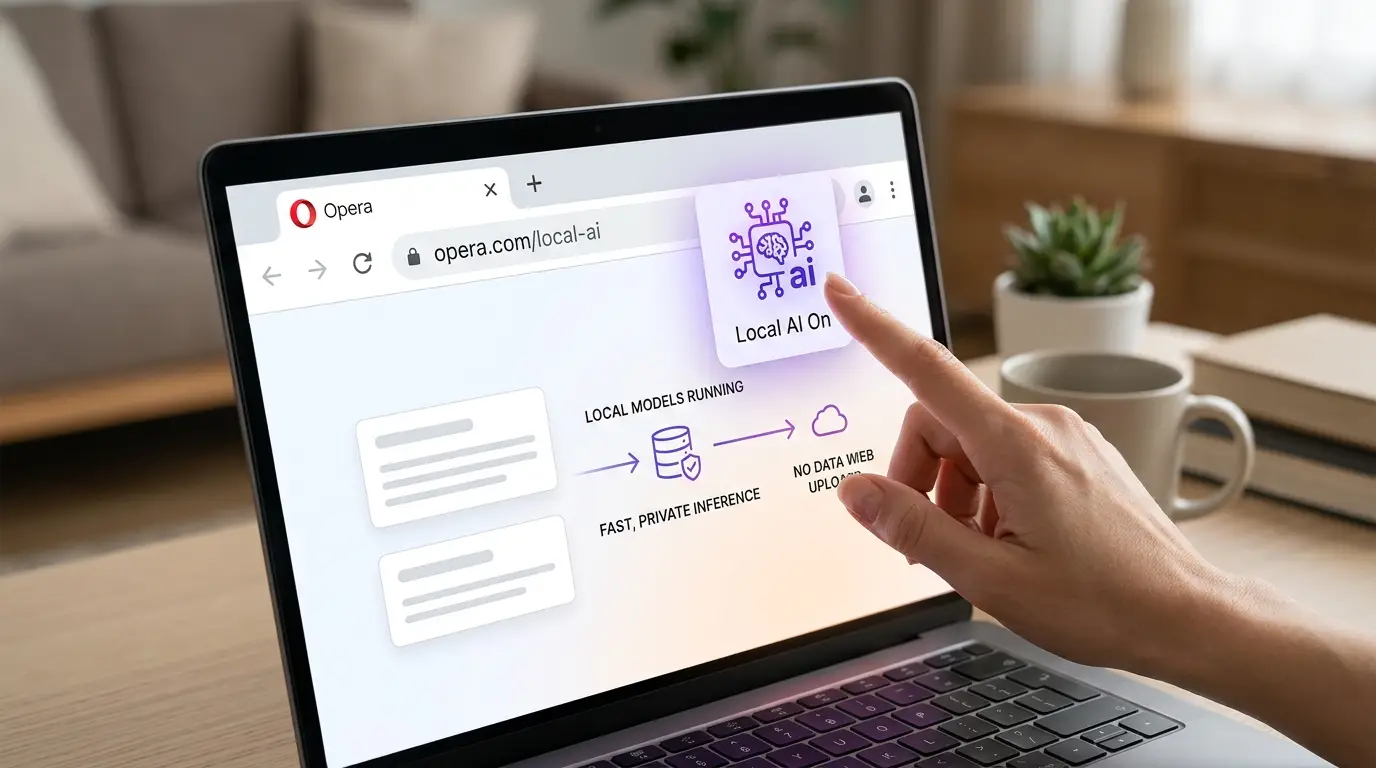
The race to put generative intelligence into every software application usually involves sending your data straight to a massive, remote server farm. Browser maker Opera is taking a radically different approach by moving the heavy lifting directly back to your laptop. The company recently rolled out an early preview of a proposed web standard called WebAI, allowing websites and extensions to execute machine learning models locally without touching the cloud.
Cutting the Cord on Cloud Dependencies
Traditionally, integrating smart features into a webpage requires developers to ping external APIs, rack up token costs, and hand over user data to third-party servers. WebAI fundamentally changes that dynamic by baking an inference engine right into the browser shell.
Because the processing happens on-device, the system inherently solves the biggest headache in modern tech: privacy. When you ask a cloud-based chatbot to summarize a sensitive financial document or draft an email, that text lives on a corporate server. With Opera’s new framework, the data never leaves your machine. Krystian Kolondra, the EVP of Browsers and AI at the company, noted that a vast majority of everyday machine learning tasks simply do not require a massive data center when modern consumer hardware is more than capable of handling the workload. This local-first architecture also means extensions can react in real-time to the exact webpage you are currently viewing, parsing the DOM without shipping the HTML payload across the internet.
A Standard Backed by Tech Giants
Opera is not trying to build a walled garden here. The framework is designed to play nicely with various open-weight architectures. Right now, the implementation fully supports lightweight systems like Google’s Gemma family, and on compatible Macs, it can even tap directly into Apple’s native foundation models.
To give builders actual tools to work with, the standard introduces three distinct interfaces: Prompt for generating text, Decision for classifying content, and Semantic Embeddings for understanding contextual relationships between different pieces of information. This opens the door for indie developers to code highly personalized extensions, like a tool that automatically highlights job postings on a scrolling feed, filters out clickbait headlines based on your reading history, or generates a quick reading comprehension quiz for a long-form news article without ever worrying about server maintenance or API billing limits.
| Feature Category | Cloud-Based AI Integration | Local WebAI Execution |
| Data Privacy | Sent to remote servers for processing | Remains strictly on the user's physical device |
| Developer Costs | Pay-per-token pricing based on API usage | Zero inference costs after initial model download |
| Latency Profile | Dependent on network speed and server load | Dictated purely by local CPU and RAM capabilities |
| Offline Capability | Requires a constant internet connection | Fully functional without any network access |
Hardware Realities and Early Adoption
Running neural networks on your own silicon is not entirely free, though the cost is paid in battery life and thermal output rather than monthly subscriptions. The initial rollout is currently available to Opera One users running 64-bit Windows machines with Intel or AMD chips, as well as Macs equipped with Apple silicon.
Users must explicitly opt into the feature via the settings menu, which triggers a one-time download of the required model weights. While the processing speed will naturally depend on the physical hardware sitting on your desk, giving the community this level of granular control represents a massive shift. Instead of renting intelligence by the millisecond, the web is finally starting to let you own it.
Popular news
Nvidia CEO Jensen Huang Admits to an Affair as Company Probes Possible Chinese Espionage
Nvidia Tightens AI GPU Tracking in Southeast Asia to Prevent Smuggling
Nvidia Board Launches Probe Into Foreign Intelligence Reports Targeting CEO
Valve Updates Steam Release Rules to Manage AI Game Surge
Singapore General Hospital Wins Global Healthcare Award For Antibiotic AI Tool