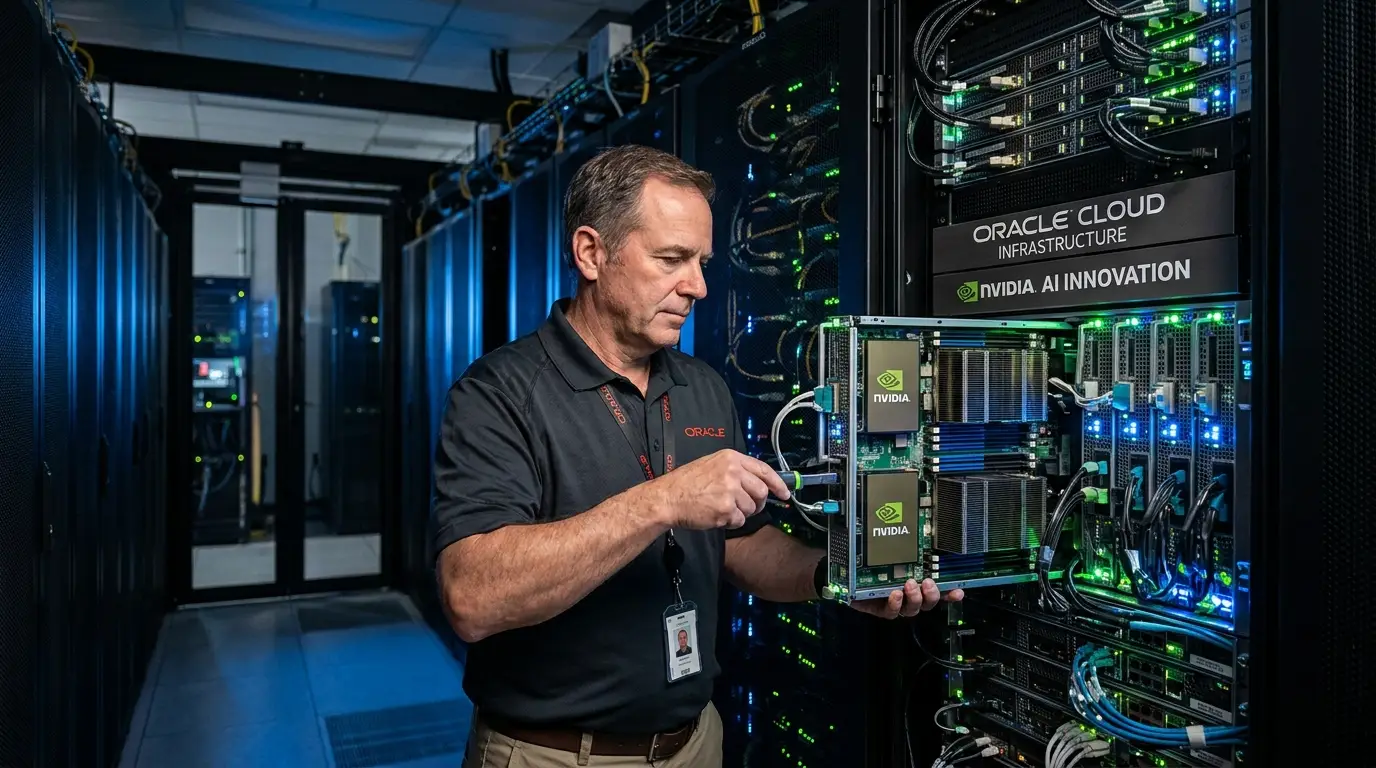
Nvidia and Oracle recently expanded their artificial intelligence infrastructure partnership. The collaboration introduces general availability of Vera Rubin NVL72 systems and standalone Vera CPUs on Oracle Cloud Infrastructure. This move addresses two major enterprise demands. Companies need massive computing power to train advanced models. They also require substantial central processing unit capacity for AI agents to execute code and retrieve information between model calls.
The companies argue that allowing customers to scale central processing unit and graphics processing unit resources separately reduces unused capacity. This efficiency pitch targets a known industry problem. Recent VentureBeat Intelligence surveys reveal that 79 percent of enterprise respondents report graphics processing unit utilization at 50 percent or below. Most of these organizations still plan platform changes despite the low usage.
Buyers must diagnose what prevents existing resources from doing useful work before investing in new hardware. A graphics processing unit waiting for a central processing unit to finish executing code presents a different purchasing problem than a unit with no queued work. Faster processors could help the former scenario. They will not create demand for the latter. If the constraint lies in remote services or application design, a processor upgrade alone leaves the underlying problem unresolved.
Oracle Cloud Infrastructure plans to deploy hundreds of thousands of these new processors. The official Oracle announcement highlights that the Vera CPU delivers 80 percent faster agentic performance compared to leading x86 alternatives. This architecture features 88 custom cores and high bandwidth memory designed specifically for concurrent AI agent tasks.
| Component | Primary Function | Target Workload Benefit |
| Vera Rubin NVL72 | Graphics processing acceleration | Frontier model training and serving |
| Standalone Vera CPU | Orchestration and tool execution | Reducing graphics processing unit idle time |
| Oracle Acceleron | Hardware isolation and networking | Secure execution of untrusted generated code |
| HGX Rubin NVL8 | Flexible x86 server configuration | Adapting to evolving model requirements |
The planned expansion builds on existing infrastructure supporting massive model training. OpenAI already utilizes Oracle Superclusters with over 100000 Nvidia Blackwell graphics processing units in Abilene. Engineering leaders note that this infrastructure provides the computing performance needed to accelerate model training and serve demanding workloads.
Nvidia emphasizes that artificial intelligence factories must remain productive and useful through continued software advances. The partnership aims to help customers put more of their infrastructure to work today. Sustaining this value requires matching hardware capabilities with actual workload demands. The official Nvidia platform details confirm that the new architecture supports up to 170 gigabytes per second of unified memory bandwidth. This specification ensures that data intensive operations do not stall the primary graphics processing units.
Organizations must align their procurement strategies with actual operational needs rather than chasing raw hardware specifications. The industry shift toward agentic systems requires a holistic view of the entire compute stack. Balancing central processing and graphics processing resources will define the next phase of enterprise artificial intelligence adoption. By decoupling the orchestration layer from the model execution layer, organizations can achieve a more balanced and cost effective infrastructure deployment.
Popular news
Steam Next Fest Top Demos Reveal Player Preferences Beyond AI Hype
AI Reverse Engineering Movement Revives Old Gadgets and Strips Smart TV Ads
Podcast: Google's Genie 4 gives AI worlds a soundtrack
Google’s Genie 4 Creates Interactive Worlds with Sound
OpenAI and Anthropic Announce Major Artificial Intelligence Developments in Late 2026
MIT Researchers Observe AI Agents Playing Without Assigned Tasks
Latest comments
Loading