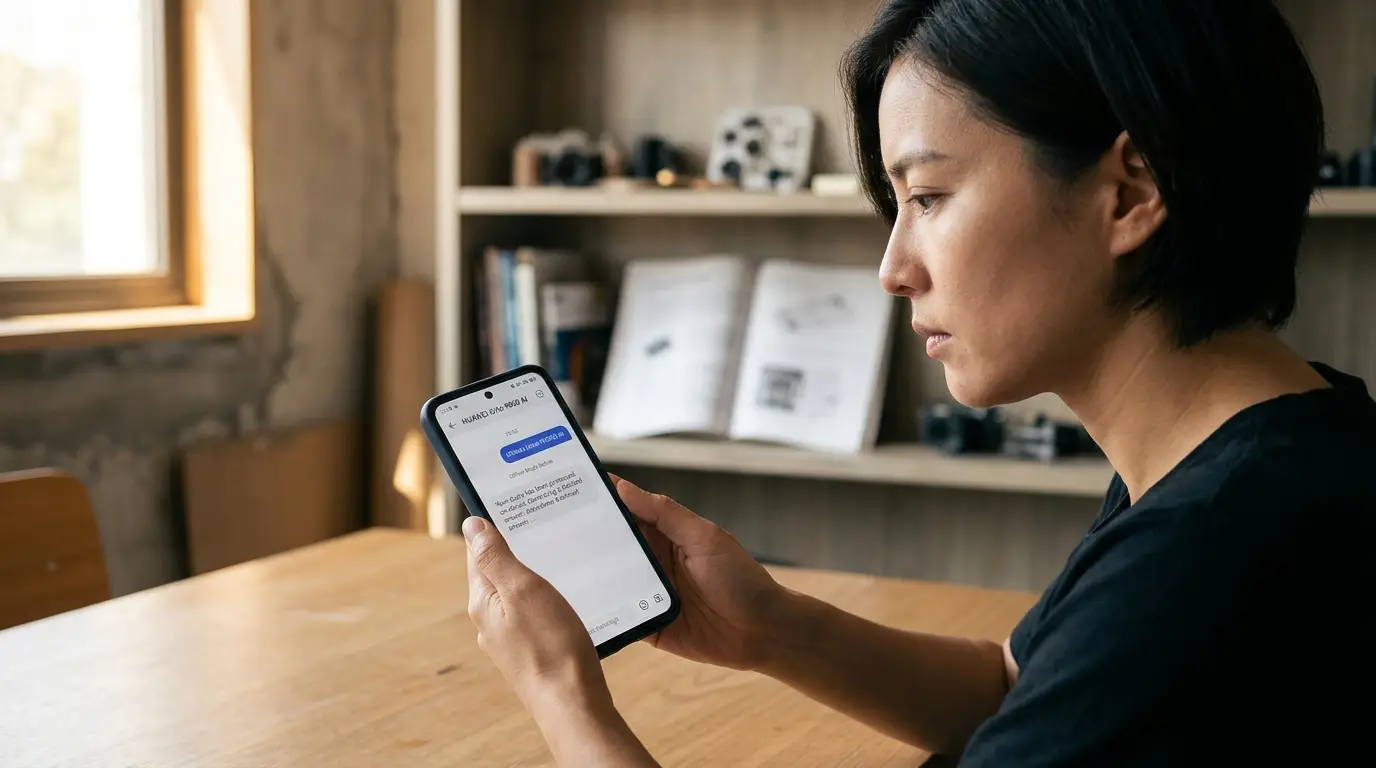
Running a massive language model usually requires a trip to a distant server farm, but mobile silicon is finally catching up to the cloud. According to a recent technical breakdown published by TechNode, Huawei just pulled back the curtain on how its newest mobile processor manages to run a staggering 30-billion parameter model entirely on a smartphone without touching the internet.
Engineering the Da Vinci Neural Engine
The secret to this local processing feat lies in aggressive hardware specialization and clever mathematical shortcuts. The Kirin 9050 relies heavily on Huawei's proprietary Da Vinci architecture for its neural processing unit. Instead of trying to fire all 30 billion parameters simultaneously—which would instantly drain a phone battery and overheat the chassis, the system utilizes a Mixture-of-Experts routing mechanism.
When you ask the device a question, the chip wakes up only about 2 billion active parameters to process the specific query. By combining this selective activation with extreme low-bit quantization, the silicon dramatically shrinks the model's memory footprint. This tight coordination between the compute blocks and the memory controller allows the phone to handle complex reasoning tasks locally.
Software Ecosystem and User Features
Hardware only gets you halfway there. To make these heavy models useful, the underlying software stack must be perfectly optimized to prevent bottlenecking. This is where the Compute Architecture for Neural Networks steps in, providing a unified execution environment that translates complex AI instructions directly to the mobile hardware.
As the industry shifts heavier workloads to the edge, the financial and technical landscape of localized computing is evolving rapidly.
| Edge AI Infrastructure Metric | 2024 Industry Baseline | 2026 Current Capabilities |
| Global Edge AI Market Valuation | $26.4 Billion | $68.2 Billion |
| Average Mobile NPU Bandwidth | 65 GB/s | 135+ GB/s |
| Standard On-Device LLM Footprint | 7 Billion Parameters | 30+ Billion Parameters |
| Inference Latency (Local vs Cloud) | ~120ms | < 15ms |
Market and hardware metrics reflect broader semiconductor advancements and edge computing adoption rates across the global mobile sector.
The Push for Total Privacy
Beyond raw speed, keeping a 30-billion parameter brain trapped inside a pocket device solves a massive privacy hurdle. User data, personal emails, and private photos never have to leave the physical handset to be analyzed by an algorithm. This hardware push perfectly mirrors the broader strategy behind HarmonyOS NEXT, which deeply embeds native machine learning directly into the operating system layer rather than treating it as a third-party app.
Currently, this offline horsepower powers practical daily utilities like intelligent screen reading and eye-tracked page turning. However, as mobile memory bandwidth continues to scale, the line between what a desktop GPU can do and what your morning commute companion can handle is rapidly vanishing.
Popular news
EU Leaders Meet in Dublin to Decide Who Pays for Europe’s AI Computing Power
Google DeepMind’s AlphaGenome 2 predicts what DNA variants do in specific cells
Anthropic Bankers Push IPO Pricing Above Initial Range to Reach 1.5 Trillion Valuation
Anthropic Says Automated Coding Tools Are Dismantling Nvidia Software Moat
US Data Brokers Supply Half Billion Dollars In AI Training Environments To Chinese Labs