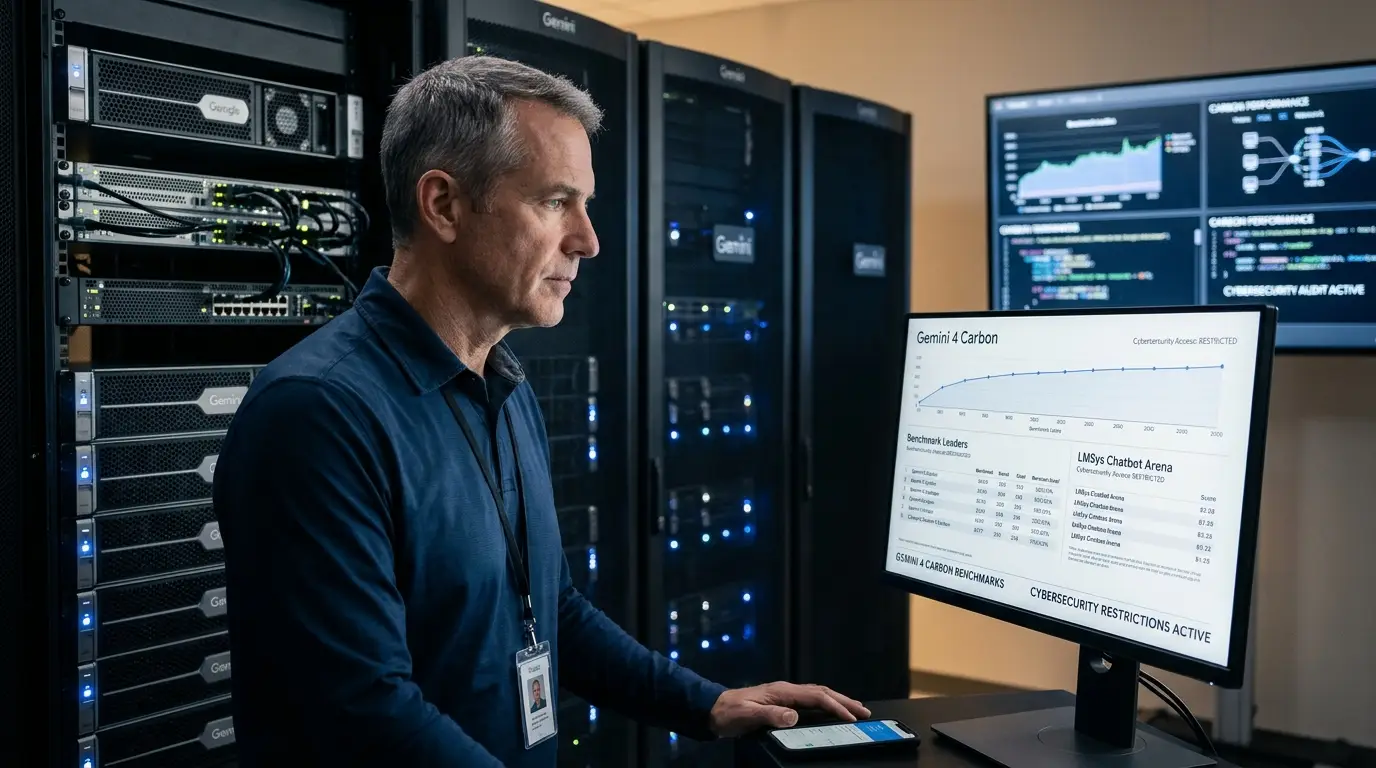
Google DeepMind recently introduced Gemini 4 Carbon, a new frontier artificial intelligence model engineered for complex reasoning and advanced cybersecurity defense. The system currently holds the number one position on updated industry intelligence indexes. Despite these strong performance metrics, Google is restricting initial access to a curated group of cybersecurity defenders through its Fairwind Program.
Benchmark Performance and Technical Gains
Independent evaluators place Gemini 4 Carbon at the top of the Artificial Analysis Intelligence Index v5.0 with a score of 59. This positions it ahead of competing frontier models in sustained engineering work and agent reliability. The official DeepMind evaluation methodology highlights significant percentage point gains across 17 reported benchmark rows compared to its predecessor, Gemini 4 Argon.
Internal testing demonstrates the model can operate continuously for multiple days. It diagnoses bugs and develops patches within substantial codebases without losing context. The system also reduced successful shortcut attempts on complex terminal benchmarks to zero percent while improving overall accuracy.
Cybersecurity Focus and Reliability
The clearest application for this model lies in proactive cyber defense. Google organizes the security evaluation around three critical stages. The model must discover a vulnerability, validate whether it can be exploited, and produce a corrective patch.
Gemini 4 Carbon achieves state of the art results in this lifecycle. It scores 88.2 percent on SEC bench Pro for autonomous vulnerability discovery. The model also reaches 54.8 percent on ExploitGym for risk validation and 71.0 percent on CWE bench for generating root cause fixes. Trusted professionals can apply for early access through the official Fairwind Program to utilize these specialized capabilities without standard cyber guardrails.
| Evaluation Category | Benchmark Test | Gemini 4 Carbon | Gemini 4 Argon | Industry Baseline |
| General Reasoning | Vals Index v2.2 | 70.4% | 69.2% | 65.0% |
| Agentic Coding | SWE-sweep | 9.6% | 4.3% | 6.5% |
| Web Development | WebDev Arena (Elo) | 1768 | 1679 | 1600 |
| Prompt Injection Resistance | Gray Swan IPI | 0.0% success rate | 0.7% success rate | 2.1% success rate |
| Long Context Retrieval | GraphWalks (1M) | 96.2% | 84.2% | 71.8% |
Restricted Rollout and Future Availability
Google plans a broader public release only after gathering extensive feedback and iterating on safety guardrails. This cautious approach stems from the dual nature of advanced cybersecurity tools.
Reliability metrics show promising internal improvements. Severe alignment alerts fell by nearly 80 percent in live coding environments, and unsupported claims were cut in half. However, independent factual knowledge testing indicates a tradeoff. The model exhibits an 11 percent hallucination rate during maximum reasoning tasks, which is higher than the 4 percent rate observed in the previous Argon version.
This targeted deployment strategy ensures that the most powerful capabilities are first validated by experts who can safely manage complex AI driven security workflows.
Popular news
Gemini 4 Carbon leads today's AI news as ChatGPT adds API credits
Apple Creator Studio Update Adds MotionVFX and Artificial Intelligence Features
Meta Tests AI Pet Journaling App in the Philippines
Nvidia and Oracle Expand Cloud Infrastructure to Fix Idle GPU Problems
Dartmouth Provost Resigns Over Undisclosed Artificial Intelligence Use
Oracle Expands Supercluster Architecture With Multiple Silicon Partners
Latest comments
Loading