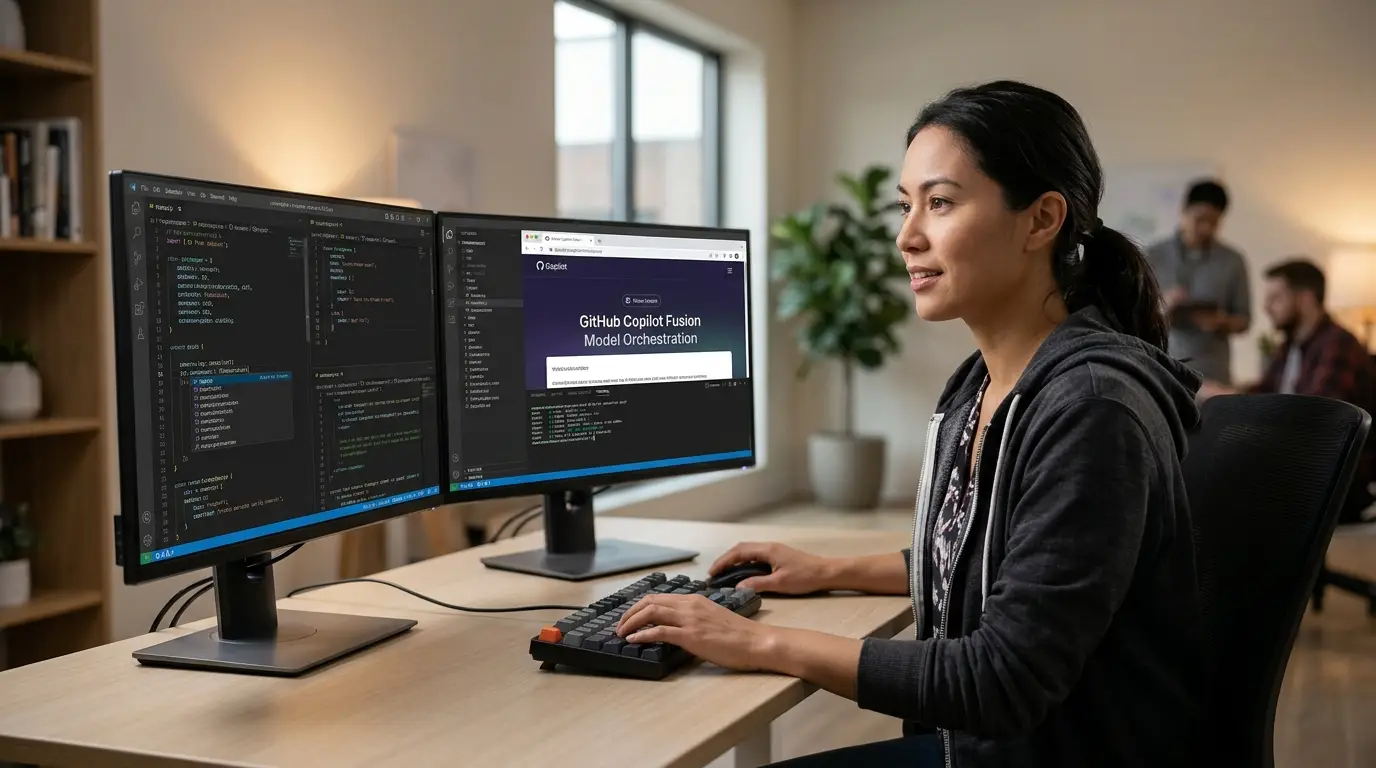
Microsoft subsidiary GitHub recently introduced Copilot Fusion. This new system dynamically routes software development tasks among various artificial intelligence models. Independent testing indicates the platform achieves performance levels comparable to top tier coding agents while reducing expenses by roughly half.
GitHub unveiled the technology at its annual developer conference. The system evaluates requests involving reasoning, code generation, debugging and tool usage. It then decides whether to assign the work to a single model or coordinate multiple models to complete the objective. This approach builds upon earlier research initiatives focused on automated model selection.
Intelligent Model Routing
Developers now encounter this technology as a selectable mode rather than an isolated model. Users can enable three distinct reasoning effort levels. The standard level prioritizes versatile models for routine coding. The high level targets more complex development work. The max level aims at the most demanding programming tasks.
Execution Patterns and Documentation
The platform utilizes three specific execution patterns to optimize performance. The single pattern sends work directly to the most suitable model. The cascade pattern begins with a cost effective model and escalates to a stronger one only if necessary. The critique pattern has one model draft a response while another reviews it before the original model revises the output. These operational details are clearly outlined in the official GitHub Copilot documentation.
| Execution Strategy | Operational Mechanism | Token Consumption Profile | Optimal Development Scenario |
| Single | Direct assignment to primary engine | Minimal | Routine syntax adjustments |
| Cascade | Initial lightweight processing with conditional upgrade | Moderate | Feature implementation requiring validation |
| Critique | Sequential drafting and independent verification | Elevated | Critical infrastructure or security modifications |
Independent Benchmark Results
Independent benchmarks provide concrete data on these claims. Artificial Analysis tested the max setting through the command line interface. The results showed Fusion completing tasks at an average cost of $5.59. This figure represents a 51 percent reduction compared to the $11.42 average cost of running Claude Code with Opus 5.5 at its maximum setting. The detailed methodology and results are available in the official Artificial Analysis Coding Agent Index.
Fusion also finished benchmark tasks approximately 40 percent faster than the competing configuration. The system consumed roughly 7.2 million tokens per task. This token usage is about half of what the Opus 5.5 configuration required. The savings stem from executing less overall model work rather than merely substituting cheaper tokens.
Performance varied across different evaluation categories. Fusion led competing systems on terminal benchmark tests with a score of 71. It scored 51 on repository change evaluations, trailing slightly behind other advanced configurations. These metrics demonstrate that while the composite score is highly competitive, the system does not dominate every specific type of coding assignment.
The introduction of this orchestration engine marks a shift in how developers interact with artificial intelligence. Programmers can now focus on their software objectives without constantly managing underlying model selections. Organizations seeking to optimize their engineering budgets will find this orchestration layer particularly valuable for scaling development workflows efficiently.
Popular news
Gemini 4 Carbon leads today's AI news as ChatGPT adds API credits
Apple Creator Studio Update Adds MotionVFX and Artificial Intelligence Features
Meta Tests AI Pet Journaling App in the Philippines
Nvidia and Oracle Expand Cloud Infrastructure to Fix Idle GPU Problems
Dartmouth Provost Resigns Over Undisclosed Artificial Intelligence Use
Oracle Expands Supercluster Architecture With Multiple Silicon Partners
Latest comments
Loading