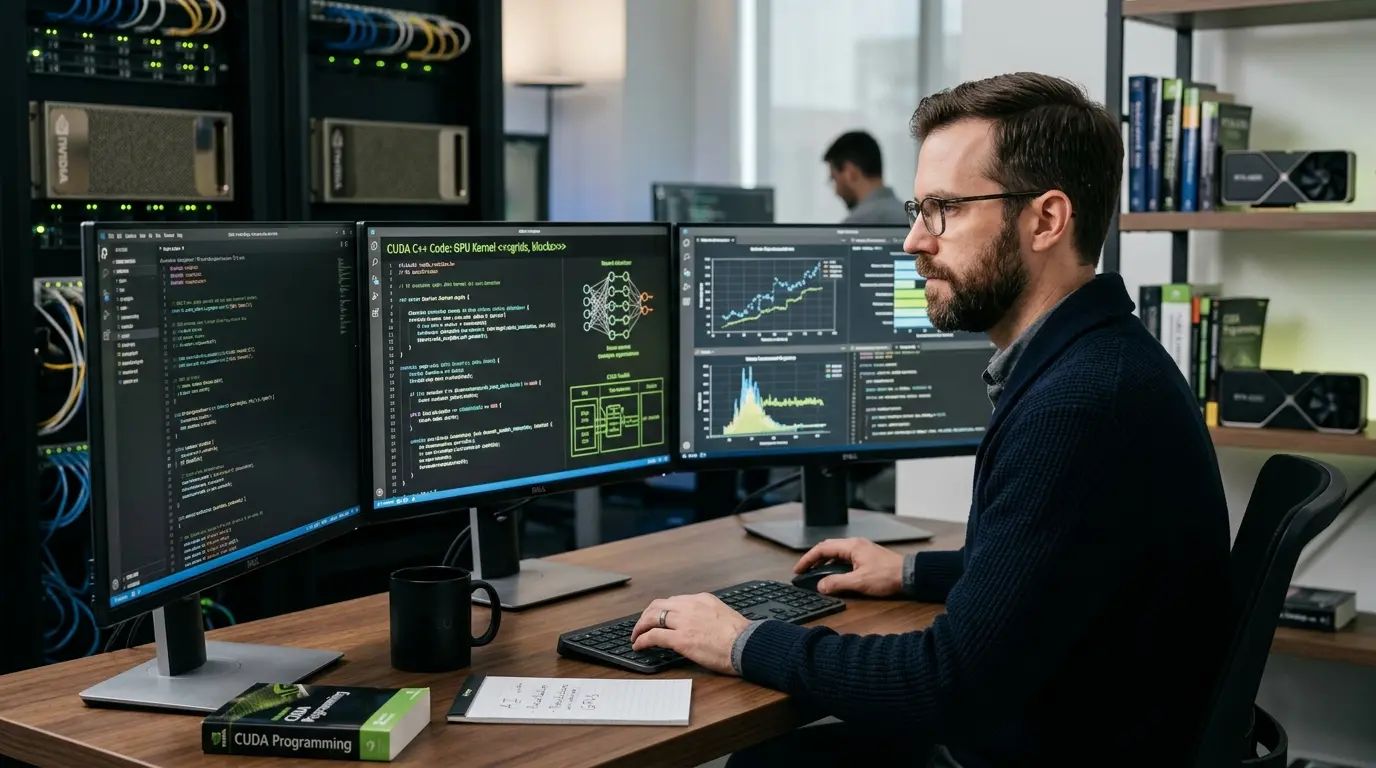
CUDA is Nvidia's parallel-computing platform and programming model for using Nvidia GPUs beyond traditional graphics. Developers can write or run software that sends suitable calculations to thousands of parallel GPU execution units, while the CPU continues to handle general-purpose work and control flow.
The name is also used more broadly. “CUDA support” can refer to the Nvidia driver, CUDA runtime, compiler, developer toolkit, mathematical libraries, profiling tools or a framework build that knows how to call Nvidia-optimized kernels. That wider ecosystem—not one language feature—helps explain why CUDA became one of Nvidia's most important competitive advantages.
This guide focuses on the software platform. For the hardware generations beneath it, read our guide to Nvidia AI GPUs. For the complete Nvidia stack from processors to racks and enterprise software, use our Nvidia AI cornerstone.
CUDA at a glance
| Question | Short answer |
| What is CUDA? | Nvidia's platform and programming model for general-purpose parallel computing on Nvidia GPUs |
| Is CUDA a programming language? | Not by itself; developers commonly use CUDA extensions and libraries from C++, Python and other environments |
| Is CUDA the same as a GPU driver? | No. The driver is one required layer; CUDA also includes runtimes, compilers, libraries and tools |
| Is CUDA free? | The toolkit can be downloaded without a software purchase, although use remains subject to Nvidia's license terms |
| Does PyTorch use CUDA? | CUDA-enabled PyTorch builds can dispatch tensor operations to Nvidia GPUs through CUDA libraries and kernels |
| Can CUDA run on AMD GPUs? | Official CUDA targets Nvidia hardware. Portability layers and code-conversion projects exist, but native AMD computing uses ROCm |
| What is CUDA-X? | A collection of accelerated libraries, tools and domain technologies built on the CUDA platform |
| Why is CUDA a moat? | It combines mature tooling, optimized libraries, broad framework support, training and a large installed developer base |
| What are the main alternatives? | AMD ROCm, OpenCL, SYCL, vendor-specific cloud stacks and compiler layers such as Triton |
| Do users need to write CUDA code? | Often not; frameworks and applications can use CUDA underneath without custom kernels |
CUDA is more than “CUDA cores”
Consumer GPU descriptions often mention CUDA cores. These are Nvidia's scalar processing units used for parallel work. CUDA the platform is different. It is the software environment that lets programs schedule and execute work on Nvidia GPUs.
The distinction matters:
- a CUDA core is a hardware execution resource;
- CUDA is a programming model and software ecosystem;
- Tensor Cores are specialized hardware for matrix operations;
- and an AI framework can use all of those resources through optimized libraries without exposing them directly to the user.
Counting CUDA cores across architectures is not a reliable way to compare AI performance. Clock speed, Tensor Cores, precision, memory, bandwidth, software and system topology all matter.
The main parts of the CUDA platform
Nvidia driver
The GPU driver lets the operating system and applications communicate with Nvidia hardware. It contains the driver API and establishes which CUDA runtime versions the system can support.
A common source of confusion is that nvidia-smi can display a “CUDA Version” even when the full developer toolkit is not installed. That field generally indicates the maximum CUDA version supported by the installed driver, not necessarily the version used to compile an application.
CUDA runtime
The runtime provides higher-level functions for allocating GPU memory, launching kernels, synchronizing work and managing devices. Many applications use it indirectly.
CUDA Toolkit
The CUDA Toolkit includes the compiler toolchain, headers, libraries, debugging and profiling tools, sample code and documentation used to develop CUDA applications.
As of August 7, 2026, Nvidia's archive lists CUDA Toolkit 13.3.1 as a current stable release and 13.4.0 as a developer preview. That statement is deliberately dated: drivers, toolkit releases and framework support change frequently. Use the official CUDA Toolkit archive before installing or standardizing a version.
CUDA compiler
nvcc is Nvidia's CUDA compiler driver. It separates and compiles code intended for the CPU and GPU, then coordinates the output with the host compiler and CUDA libraries.
Not every CUDA workload is written in CUDA C++. Python libraries, frameworks and domain applications can generate or invoke GPU kernels through lower-level components.
CUDA libraries
Nvidia supplies libraries optimized for common tasks. Examples include:
- cuBLAS for dense linear algebra;
- cuDNN for deep-neural-network operations;
- cuSPARSE for sparse matrices;
- cuFFT for fast Fourier transforms;
- NCCL for collective communication among GPUs;
- TensorRT for optimized inference;
- and RAPIDS libraries for GPU-accelerated data science.
A framework can call these libraries instead of reimplementing every operation. That is one reason software maturity can matter more than a chip's theoretical peak performance.
Developer tools
Nvidia provides debuggers, profilers and performance-analysis tools, including Nsight products. These help developers find memory bottlenecks, synchronization delays, inefficient kernels and underused hardware.
CUDA-X
CUDA-X is Nvidia's umbrella for accelerated libraries, tools and technologies across AI, data processing, scientific computing and industry applications. CUDA is the foundation; CUDA-X is the wider application and library layer built on it.
How the CUDA programming model works
A CUDA application commonly divides work between a host and a device.
- The host is usually the CPU and its memory.
- The device is the Nvidia GPU and its memory.
- A kernel is a function executed on the GPU by many threads.
- Threads are grouped into blocks.
- Blocks form a grid for a kernel launch.
A simplified flow looks like this:
- prepare data on the CPU;
- allocate memory accessible to the GPU;
- transfer or map the input;
- launch a kernel across many threads;
- synchronize or coordinate asynchronous work;
- copy or expose the result;
- free resources.
Modern frameworks hide much of this. The model still matters when performance is poor, memory runs out or a custom operation must be implemented.
Threads, blocks and grids
CUDA exposes a hierarchy that lets the same kernel operate on many pieces of data.
Thread
A thread executes one instance of a kernel. It commonly handles one element or a small group of elements.
Block
Threads within a block can cooperate through shared memory and synchronization. Block size affects occupancy and performance.
Grid
A grid contains all blocks launched for a kernel. Blocks can be scheduled across the GPU's multiprocessors.
The hardware executes threads in groups called warps. Branches that make threads in one warp follow different paths can reduce efficiency. Developers therefore think about memory access, control flow and occupancy as well as mathematical work.
CUDA memory hierarchy
GPU performance often depends on moving data efficiently.
Important memory levels include:
- registers private to threads;
- shared memory available within a thread block;
- local memory used when thread-private data spills;
- global device memory, usually HBM or GDDR;
- constant and texture memory for particular access patterns;
- and host memory connected through PCIe or coherent platform links.
Faster memory is generally smaller and more local. A good kernel reuses data close to the compute units and avoids unnecessary transfers.
This is why GPU memory capacity and bandwidth matter so much for AI. A model can have enormous theoretical compute available and still wait on weights, activations or attention-cache data.
A minimal CUDA example
The following CUDA C++ kernel adds two vectors. It is intentionally small; production code needs error handling, resource management and validation.
#include
__global__ void add_vectors(const float* a, const float* b, float* c, int n) {
int i = blockIdx.x * blockDim.x + threadIdx.x;
if (i < n) {
c[i] = a[i] + b[i];
}
}
int main() {
const int n = 1 << 20;
const size_t bytes = n * sizeof(float);
float *a, *b, *c;
cudaMallocManaged(&a, bytes);
cudaMallocManaged(&b, bytes);
cudaMallocManaged(&c, bytes);
for (int i = 0; i < n; ++i) {
a[i] = 1.0f;
b[i] = 2.0f;
}
const int threads = 256;
const int blocks = (n + threads - 1) / threads;
add_vectors<<>>(a, b, c, n);
cudaDeviceSynchronize();
cudaFree(a);
cudaFree(b);
cudaFree(c);
return 0;
}
The kernel is marked __global__, launched with a grid and block configuration, and executed once per thread. Unified memory keeps the example compact, but explicit memory strategies can be better for performance-sensitive applications.
Using CUDA through Python and PyTorch
Many AI developers never write a kernel. They use PyTorch, TensorFlow, JAX, CuPy or a higher-level application.
A basic PyTorch check is:
import torch
print("PyTorch version:", torch.__version__)
print("CUDA available:", torch.cuda.is_available())
if torch.cuda.is_available():
print("GPU:", torch.cuda.get_device_name(0))
x = torch.randn(4096, 4096, device="cuda")
y = x @ x
print(y.shape)
This confirms only that the framework can see and use a device. It does not prove that drivers, libraries and kernels are optimal for the workload.
Useful environment checks include:
nvidia-smi
nvcc --version
python -c "import torch; print(torch.__version__, torch.version.cuda, torch.cuda.is_available())"
The three outputs can legitimately show different version information: driver capability, installed toolkit and the CUDA version against which the framework build was compiled.
Why CUDA matters to PyTorch and AI frameworks
A high-level operation such as matrix multiplication can trigger a chain of optimized components:
- the framework constructs and schedules tensor operations;
- a dispatcher selects the Nvidia backend;
- CUDA libraries or generated kernels implement the operation;
- NCCL coordinates work across multiple GPUs;
- the driver schedules work on the hardware;
- profiling and monitoring tools expose performance.
This layered approach means users can benefit from CUDA without writing device code. It also means a model's compatibility depends on more than the top-level framework name.
A PyTorch project can contain:
- custom CUDA extensions;
- third-party packages with compiled kernels;
- Triton kernels targeting Nvidia behavior;
- container images tied to particular drivers;
- TensorRT or TensorRT-LLM engines;
- and distributed-training assumptions built around NCCL.
Those dependencies must be audited before migrating hardware.
What is Nvidia's CUDA advantage?
Maturity
CUDA has been developed since 2006. Drivers, libraries, documentation and tools have accumulated across many hardware generations.
Framework priority
New AI methods are often optimized for Nvidia early because researchers and providers have access to Nvidia systems and because CUDA is a common production target.
Libraries
A highly optimized library can save years of engineering. Users benefit without having to create every kernel themselves.
Developer base
Universities, researchers, cloud providers, software vendors and enterprises train people on CUDA. Skills and examples are widely available.
Hardware availability
Nvidia accelerators can be rented or purchased through many clouds, GPU providers and system manufacturers. Software developers therefore have a reason to support them.
Full-stack integration
CUDA connects to Nvidia's GPUs, NVLink, NCCL, TensorRT, NIM, DGX and enterprise products. That integration can improve deployment speed and support.
Is CUDA vendor lock-in?
CUDA creates both genuine value and switching cost.
Calling every dependency “lock-in” can obscure useful engineering. A company may choose CUDA because it reduces development time, improves performance and has better production support. Those benefits are real.
The dependence becomes risky when the organization:
- cannot identify CUDA-specific code and packages;
- assumes another accelerator will run the workload unchanged;
- lacks tests for output quality and performance;
- signs long commitments without an exit path;
- or uses proprietary features where portable alternatives would have met the requirement.
The correct response is not necessarily to avoid CUDA. It is to know where the dependency exists and decide whether its value justifies the cost.
CUDA alternatives
AMD ROCm
ROCm is AMD's open-source GPU-computing platform with compilers, runtimes, libraries and framework support. It is the closest direct alternative for AMD Instinct accelerators.
ROCm has improved rapidly, but compatibility varies by GPU, operating system, library and framework. Our Nvidia versus AMD guide compares the complete environments.
OpenCL
OpenCL is an open standard for heterogeneous computing. It can target devices from multiple vendors, but AI framework and library depth may differ from CUDA for a given workload.
SYCL and oneAPI
SYCL provides a C++ programming model for heterogeneous systems. Intel's oneAPI ecosystem uses it prominently. Portability still requires supported implementations, libraries and testing.
Triton
The Triton language and compiler can make custom GPU kernels easier to express than low-level CUDA C++. Triton is not automatically hardware-neutral in practice; backend support and generated-kernel quality matter.
Cloud-specific stacks
Google TPU, AWS Trainium and Microsoft Maia use their own compilers, SDKs and framework integrations. They can offer attractive economics inside one cloud while increasing provider dependence.
CPU and specialist accelerators
Some inference, data-processing or edge workloads run more economically on CPUs, integrated accelerators or specialist hardware. “AI workload” does not automatically mean “buy the largest GPU.”
How to reduce CUDA switching risk
- Keep model code separate from device-specific optimization.
- Use standard framework operations where performance is adequate.
- Inventory custom CUDA extensions and compiled dependencies.
- Pin and document drivers, toolkit, framework and container versions.
- Maintain reproducible tests for output quality and performance.
- Avoid hard-coded device assumptions.
- Test a second backend on representative workloads before it is urgently needed.
- Measure migration effort honestly; a slow alternative can be more expensive than a proprietary one.
- Keep data, checkpoints and model formats portable where possible.
- Negotiate cloud and hardware commitments with exit and refresh cycles in mind.
CUDA version compatibility
CUDA compatibility has several layers:
- driver support for the runtime;
- toolkit and compiler version;
- GPU architecture support;
- framework build;
- library versions;
- operating system and container base;
- and third-party extension binaries.
A newer toolkit is not always the safest production choice. Frameworks and packages may lag. Conversely, an old environment may not support a new architecture or security fix.
Use a tested compatibility matrix and keep the environment reproducible. Nvidia's CUDA Programming Guide and framework documentation should be treated as primary references.
CUDA in containers and Kubernetes
Containers package user-space libraries and applications, but they do not normally include a complete host kernel driver. A container must remain compatible with the Nvidia driver on the host.
Kubernetes deployments often use Nvidia's container tooling and GPU Operator to install or manage device plugins, drivers and supporting components. Enterprise environments should define:
- approved driver branches;
- node labels and GPU types;
- partitioning and multi-instance policy;
- scheduling and quotas;
- isolation and secrets;
- image provenance;
- monitoring;
- and upgrade and rollback procedures.
The paid production software layer is covered in our Nvidia AI Enterprise guide.
Common CUDA mistakes
Installing the newest toolkit without checking the framework
The latest toolkit may not be supported by the selected PyTorch, TensorFlow or extension build.
Confusing the nvidia-smi version with the installed toolkit
The displayed value often reflects driver capability, not nvcc or the application's compiled runtime.
Copying an installer command from an unofficial page
Use Nvidia's official repository and documentation. Verify package signatures and domains according to organizational policy.
Assuming more GPU utilization means more useful work
A workload can show high utilization while processing inefficient batches or producing unacceptable latency and quality.
Ignoring data transfer
Repeated CPU-to-GPU transfers can erase expected gains. Profile the full pipeline.
Writing custom kernels too early
Framework and library operations are usually easier to maintain. Write custom code only after profiling identifies a real bottleneck.
Treating portability as a future problem
Once custom kernels, containers and operations are deeply embedded, migration becomes a major project.
Frequently asked questions
What does CUDA stand for?
Nvidia originally expanded CUDA as Compute Unified Device Architecture. Current documentation generally treats CUDA as the platform name.
Is CUDA a programming language?
No. It is a platform and programming model. CUDA C++ extends C++, and CUDA can also be accessed through Python libraries and other language bindings.
Do I need CUDA for PyTorch?
You need a CUDA-enabled PyTorch build to use Nvidia GPU acceleration. CPU, ROCm and other backend builds exist for different hardware.
Is CUDA free?
The toolkit is available without a separate purchase, but it is proprietary Nvidia software governed by license terms. Commercial enterprise support and other products can cost extra.
Can CUDA run on Windows?
Yes. Nvidia supports CUDA development and runtime use on supported Windows configurations. Linux is especially common in data-centre and AI environments.
Can CUDA use multiple GPUs?
Yes. Applications can manage multiple devices, while libraries such as NCCL support collective communication for distributed training and inference.
What is the difference between CUDA and cuDNN?
CUDA is the general platform. cuDNN is an optimized library for deep-neural-network primitives built for the CUDA environment.
What is the difference between CUDA and TensorRT?
CUDA supplies general GPU computing. TensorRT optimizes and executes inference graphs on Nvidia hardware.
Does CUDA work on every Nvidia GPU?
Support depends on the GPU's compute capability, driver, toolkit and application. Older architectures eventually lose support in newer releases.
Is ROCm as good as CUDA?
There is no universal answer. ROCm can perform very well on supported AMD hardware, but software compatibility, tooling and workload optimization must be tested. CUDA remains broader and more mature in many production environments.
Bottom line
CUDA is the software foundation that turned Nvidia GPUs from graphics devices into general accelerated-computing platforms. Its programming model lets applications express parallel work, while the toolkit, libraries, framework integrations and tools make that work practical.
The platform's value is also the source of Nvidia's switching power. Organizations build code, containers, skills and operations around CUDA because it works. They should preserve that productivity while documenting dependencies, testing portability and measuring the full workload rather than assuming either loyalty or migration is automatically cheapest.

byDavid Porter
Popular news
Millions Of Pet Owners Are Buying Into Chinas Latest AI Pet Gadget Craze
Naver and Brookfield Massive Nine Billion Dollar AI Factory Deal Shakes South Korea Tech Scene
AliExpress Dominates IFA 2026 With Chinese AI Gadgets Everyone Needs Now
Alibaba QwenWork AI Token Maxxing Strategy Destroys Existing Limits For Global Businesses
Huawei Kirin 2026 Secret Scaling Tech Leak Proves Massive Power Boost Is Coming
Saudi Arabia Teams Up With MiniMax To Build Massive Trillion Parameter Sovereign AI Model Humain M3 By September 2026
Latest comments
Loading