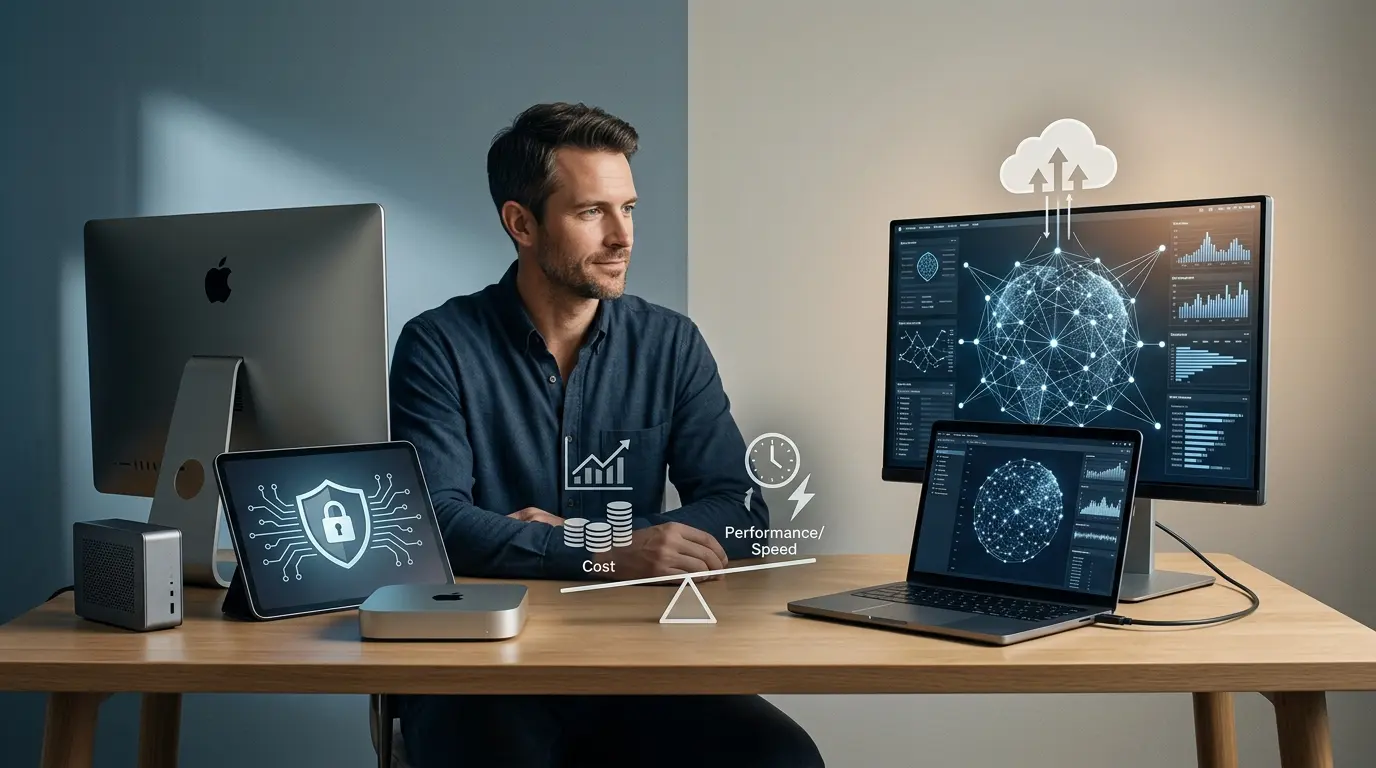
The local AI versus cloud AI choice is a trade between control and managed capability. Local AI runs a downloadable model on hardware you control. Cloud AI sends requests to provider-managed infrastructure through a website, app or API.
Local deployment is usually strongest for offline work, predictable high-volume use and data that should remain inside a device or private network. Cloud AI is usually strongest when you need a frontier model, instant scaling, managed collaboration or features that depend on current online services.
Many practical systems use both. They classify or redact data locally, route routine work to a local model and send approved high-difficulty tasks to a cloud model. The architecture should make that routing visible.
Use the Local AI hub to build the local side and AI World Today’s AI Infrastructure coverage for the systems behind hosted AI.
Local AI versus cloud AI at a glance
| Factor | Local AI | Cloud AI |
| Prompt location | Can remain on-device | Sent to provider infrastructure |
| Model capability | Limited by downloadable models and hardware | Access to managed frontier and specialist models |
| Upfront cost | Hardware, setup and engineering | Usually low; account or API access |
| Ongoing cost | Electricity, maintenance and staff | Subscription, token, tool and storage fees |
| Scaling | Fixed by owned capacity | Elastic within provider limits and budget |
| Offline use | Possible after downloads | Usually unavailable without a network |
| Updates | You choose and test versions | Provider manages infrastructure and may change products |
| Data controls | You design them | Provider, plan, region and contract define them |
| Latency | No internet round trip; hardware may be slow | Network round trip; powerful inference infrastructure |
| Collaboration | You must build identity and sharing | Often built into business products |
| Operational responsibility | Mostly yours | Shared with provider |
Neither column guarantees security, accuracy or low cost. A badly exposed local server can be less secure than a well-governed enterprise cloud deployment. A cloud subscription can be cheaper than buying an underused GPU. Compare specific configurations.
What counts as local AI?
A system is local when the inference engine and model weights run on the user’s computer, edge device or private machine under the user’s control.
Examples include:
- Ollama running a downloaded model on a laptop.
- LM Studio chatting with a GGUF model offline.
- A workstation serving a model to an internal team.
- An on-premises cluster operated by an organization.
Location and ownership are separate. A company can rent a dedicated cloud VM and self-host an open-weight model there. It controls the model stack but data still leaves user devices and reaches a data center. That is self-hosted cloud infrastructure, not on-device AI.
Likewise, a local application can call remote embeddings, web search or tools. That makes it hybrid. Read is local AI private and safe? for the full data path.
Privacy and data residency
Local AI privacy advantage
A fully local pipeline can keep prompts, documents, embeddings, indexes and answers on hardware you control. It can run offline and avoid sending sensitive text to a model provider.
This is valuable for:
- Personal journals and private archives.
- Early legal or commercial drafts.
- Source code that cannot enter an external service.
- Field work without reliable connectivity.
- Data-residency requirements that permit on-premises processing.
Local operation does not remove endpoint risks. Malware, shared accounts, unencrypted drives, logs, backups and exposed APIs can reveal the same data. The device owner becomes responsible for patching, access control and recovery.
Cloud AI privacy depends on the service
Cloud terms vary by provider, product, account type, endpoint and contract. Consumer chat, paid API and enterprise deployments can differ in training use, retention, abuse monitoring, region and zero-retention eligibility.
Do not apply one product’s policy to another. Review the exact documentation and contract. OpenAI publishes API data controls; Microsoft publishes separate Azure model data and privacy documentation; AWS documents Amazon Bedrock data protection. These examples show why “the cloud” is not one policy.
For personal AI assistants, compare AI World Today’s guides to ChatGPT privacy and security, DeepSeek safety and Mistral AI safety.
Model quality and capability
Cloud providers can serve models too large or computationally expensive for a personal machine. They can combine those models with managed web search, voice, images, code execution, connectors and safety systems.
Local models have improved rapidly and can be excellent at constrained work:
- Summarization and rewriting.
- Classification and extraction.
- Code assistance in a limited repository.
- Private document question answering.
- Repetitive structured generation.
- Domain tasks with retrieval and evaluation.
They may lag frontier cloud systems on difficult reasoning, broad knowledge, multimodal depth or complex autonomous tasks. A model that fits a laptop also has less capacity than a provider’s largest deployment in many cases.
The right test is task accuracy on your own examples. Use the best local AI models guide and measure output quality rather than selecting by parameter count alone.
Speed and latency
Local inference removes the internet round trip. It can begin immediately and remain available during an outage. Yet a CPU or low-memory laptop may generate much more slowly than a cloud accelerator.
Cloud latency includes network travel, queueing and provider processing. Powerful infrastructure can still deliver a response faster than local hardware, especially for large models. The result varies with region, load and service tier.
Separate these measurements:
- Time to first token: how long until output begins.
- Generation speed: output tokens per second.
- End-to-end task time: includes retrieval, tools and validation.
- Throughput: total work across concurrent users.
A fast one-user local chat can become slow when five users share one GPU. A cloud API can scale across users, but quotas and cost rise with traffic.
Hardware and model limits
Local capability is bounded by RAM, VRAM, storage, memory bandwidth, power and cooling. A package that fits on disk may not fit comfortably in runtime memory after context is added.
Read local AI hardware requirements for model sizing. The Ollama guide explains how to check CPU/GPU placement and allocated context.
Cloud users do not size a GPU for each request, but they still choose model, context, rate limit and spending limits. Larger context and higher-throughput tiers can cost more.
Cost: ownership versus consumption
Local AI costs
Local inference may have no per-token invoice, but it is not free. Include:
- Computer or GPU purchase.
- Electricity.
- Storage, backup and replacement hardware.
- Setup, updates and troubleshooting time.
- Security engineering.
- Staff who operate shared infrastructure.
- Opportunity cost when capacity sits idle.
A personal computer already owned for other work changes the calculation. Running a compact model on spare capacity can be very cheap. Buying a dedicated workstation for a handful of monthly prompts may be expensive.
Cloud AI costs
Cloud costs can include:
- Monthly subscriptions.
- Input and output tokens.
- Cached input, batch or priority tiers.
- Embeddings and reranking.
- File storage and vector search.
- Web search, code execution or other tools.
- Network and observability services.
Cloud starts with little hardware commitment and scales with use. High-volume stable workloads can accumulate a large bill; irregular or low-volume workloads may remain cheaper than owned hardware.
A simple total-cost model
For local AI:
Annual local cost = annualized hardware + electricity + maintenance + operating labor
Copy Raw HTMLRich Code
For cloud AI:
Annual cloud cost = subscriptions + API usage + tools + storage + integration labor
Copy Raw HTMLRich Code
Divide by successful completed tasks, not raw tokens. A cheaper model that requires extensive corrections may cost more per useful result.
Reliability and offline access
Local AI can keep working when an internet connection or provider service is unavailable. That is valuable on aircraft, remote sites, restricted networks and during provider outages.
The local machine becomes a single point of failure unless you build redundancy. A failed SSD, broken update or stolen laptop can stop the service and lose data. Backups and recovery tests matter.
Cloud platforms distribute infrastructure and handle much of the physical resilience. Your application still depends on internet access, credentials, provider availability, quotas and product continuity.
Updates, reproducibility and control
Local deployment lets you pin a model file and runtime version. This supports reproducible tests, regulated change control and the ability to keep an older model while validating a replacement.
You must track vulnerabilities, licenses, driver changes and model updates yourself.
Cloud providers patch infrastructure and release improvements. Managed updates reduce operational work, but product behavior, model aliases, limits and deprecated endpoints can change. Production systems should pin versions where the provider offers that option and maintain regression tests.
Security responsibility
Local AI concentrates responsibility in your organization:
- Secure the operating system and model server.
- Authenticate users.
- Segment networks.
- Protect files, prompts and logs.
- Review model provenance and dependencies.
- Back up and restore data.
- Monitor abuse and resource exhaustion.
Cloud security follows a shared-responsibility model. The provider secures its infrastructure; the customer still manages identities, credentials, permissions, data, integrations and application logic.
Use the AI Security hub and a structured framework such as the NIST AI Risk Management Framework to evaluate risks rather than treating deployment location as the final control.
Collaboration and governance
Cloud business products often include user provisioning, single sign-on, shared workspaces, admin policies, usage analytics and audit exports. These features can make governance easier than giving colleagues access to an ad hoc workstation.
Local software can be limited to one user or developed into an internal platform. Team deployment needs:
- Identity and role-based access.
- Source-level document permissions.
- Usage limits and audit events.
- Version and configuration management.
- A support and incident process.
The engineering effort can exceed the cost of inference itself.
Local versus cloud RAG
A RAG system parses documents, creates embeddings, stores an index, retrieves relevant chunks and asks a model to answer from them.
A fully local RAG pipeline keeps each stage local. A cloud RAG service can scale indexes and users but receives some or all source content. Hybrid RAG might store documents internally while sending only approved retrieved passages to a cloud model.
Map the exact data path with local RAG and document chat.
Local versus cloud AI agents
Agents add tools, memory and actions. Model location is one layer of the design.
A local model may still call cloud email, search or CRM tools. A cloud model can sometimes call tools inside a private network through a controlled gateway. In both cases, prompt injection, excessive permissions and unsafe actions remain concerns.
Compare the complete system using AI agent architecture and AI agent security. The local AI agents guide covers on-device model options.
When local AI is the better choice
Choose local first when several of these are true:
- Prompts or documents should remain on-device.
- The workflow must function offline.
- The task is repetitive and a compact model performs well.
- Workload volume is stable enough to use owned hardware.
- You need a pinned model and complete deployment control.
- Your team can operate and secure the environment.
When cloud AI is the better choice
Choose cloud first when:
- You need the strongest available managed model.
- Usage is irregular or difficult to predict.
- Many users need concurrent access quickly.
- Managed search, voice, image or collaboration features matter.
- You lack staff to maintain inference hardware.
- An approved enterprise cloud contract meets the data requirements.
When a hybrid architecture works best
Hybrid routing can combine strengths:
- Classify data locally.
- Handle routine or sensitive requests with a local model.
- Redact or minimize inputs before an approved cloud call.
- Send only tasks that need higher capability.
- Record which path was used.
- Keep high-risk actions behind human approval.
Do not make hybrid routing invisible. Users and administrators should know when data crosses a boundary.
FAQ
Is local AI cheaper than cloud AI?
It can be for steady high-volume work on hardware you already own. Cloud can be cheaper for occasional use or tasks that require expensive models. Compare annual total cost per successful task.
Is local AI faster?
It removes network latency, but hardware determines generation speed. A cloud GPU can outperform a local CPU. Measure time to first token and full task completion.
Is local AI always more private?
No. A fully local pipeline can minimize external transfers, but malware, exposed APIs, weak access controls and remote tools can undermine it. Enterprise cloud services may offer controls an unmanaged laptop lacks.
Can local AI work offline?
Yes, after the runtime and model are downloaded, provided the workflow does not require web search, remote embeddings or external tools.
Does cloud AI train on my data?
Policies differ by provider, product and account type. Review the exact service’s current terms and data-control documentation. Do not infer API or enterprise treatment from a consumer chat product.
Can I use both local and cloud AI?
Yes. A hybrid system can route by sensitivity, difficulty, latency or cost. Log the decision and disclose when data moves to a cloud service.
Which option is better for a business?
The answer depends on data classification, workload volume, model-quality requirements, internal expertise and approved vendors. A controlled pilot with representative tasks will reveal the operational cost better than a generic benchmark.
Final decision
Choose local AI for control, offline access and workloads that a downloadable model can perform well. Choose cloud AI for frontier capability, elastic scaling and managed product features. Choose hybrid when the data and difficulty of tasks vary.
Then test the full workflow. Use how to run AI locally for a first local deployment and the AI Agents hub when the system must move from answering to acting.
byDavid Porter
Popular news
Anthropic Researchers Warn Advanced AI Models Could Trigger Human Extinction
Andy Burnham Faces Urgent Demands to Block Artificial Superintelligence in Manchester
Senator Josh Hawley Launches Massive Investigation Into OpenAI After Critical Hugging Face Breach
UK Computer Science Graduates Face a Massive Job Market Shift Driven by AI
Anthropic Researchers Issue Urgent Warning Regarding Elon Musk and Global AI Safety Risks
OpenAI Board Member Paul Christiano Warns AI Control Could Be Lost Forever
Latest comments
Loading