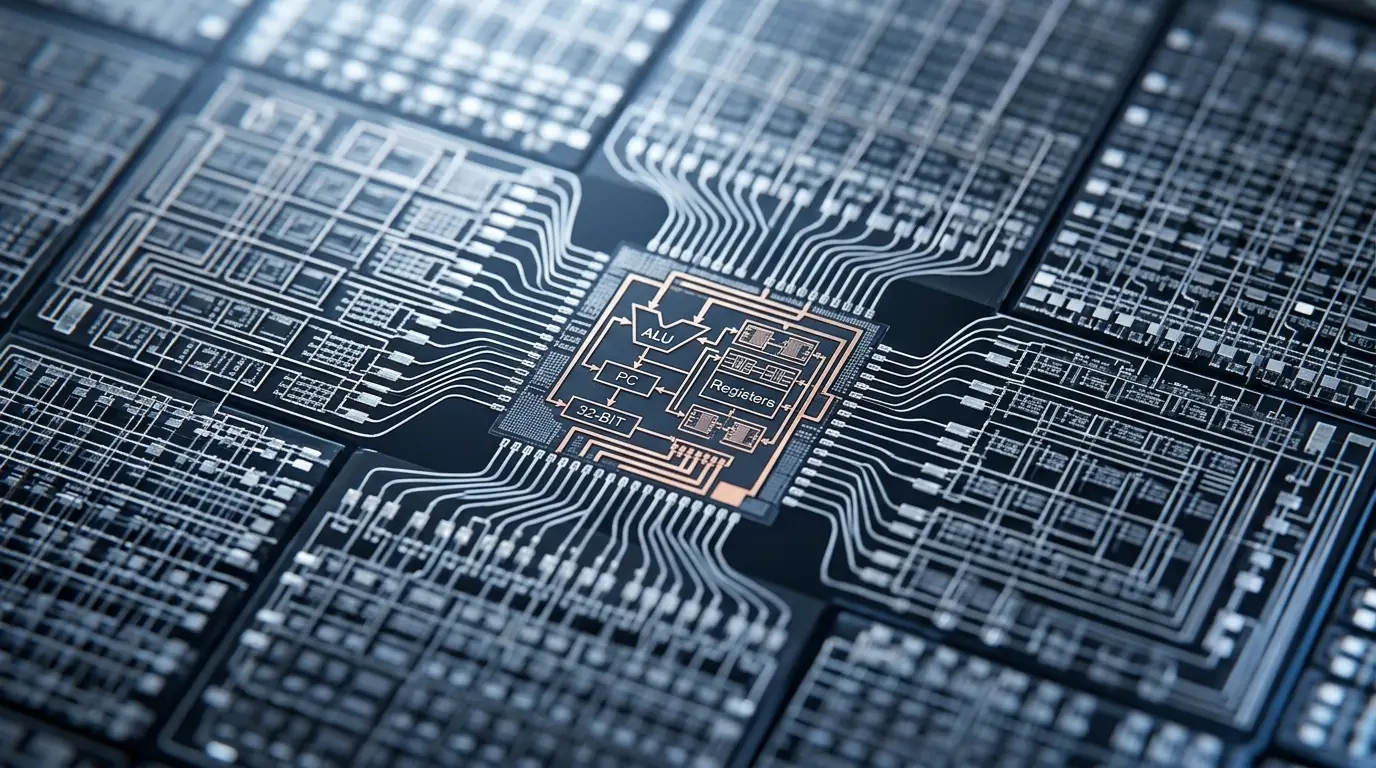
A groundbreaking experiment in artificial intelligence has blurred the line between neural networks and traditional computing. AI engineer Divyansh Agrawal recently introduced Qwenputer, an experimental project that successfully compiles a functional 32-bit RISC-V CPU directly into the weights of a large language model. This innovative approach allows the AI to execute deterministic processor arithmetic operations and run classic software without relying on external plugins.
The foundation of this project is the stock Qwen 3.5 4B model developed by Alibaba. Instead of treating the neural network solely as a text generator, Agrawal repurposed its internal architecture. According to reports from Tom's Hardware, the model uses its own Gated DeltaNet memory layers to function as exact RAM. This means the AI essentially hosts its own computing environment within its parameter space.
Technical Architecture and Capabilities
The integration is not a superficial wrapper or a simple API call. The 32-bit RISC-V processor is meticulously compiled into 11 new layers within the model itself. This architectural shift enables the system to execute standard ELF binaries, matching the output of traditional qemu-riscv32 emulation with zero discrepancies. The system successfully ran 61 distinct ELF binaries during testing, validating its reliability as a computational engine. Developers can now run C code and MicroPython scripts directly through the model inference process.
Perhaps the most viral demonstration of this capability is the successful execution of the classic game DOOM. By rendering frames through the model internal state, Qwenputer proves that neural weights can sustain complex and stateful computational loops. You can explore the open source implementation and test the binaries yourself on the official Qwenputer GitHub repository.
| Specification | Detail |
| Base Architecture | Qwen 3.5 4B Large Language Model |
| Embedded Processor | 32-bit RISC-V CPU |
| Memory Mechanism | Gated DeltaNet state acting as internal RAM |
| Total Model Size | Approximately 19 GB (doubled from original) |
| Supported Execution | C code, MicroPython, ELF binaries, DOOM |
| External Dependencies | None (fully independent within weights) |
Implications for Future AI Development
This experiment challenges conventional boundaries in machine learning hardware utilization. Traditional AI inference relies heavily on graphics processing units to perform massive matrix multiplications for token prediction. Qwenputer demonstrates that model weights can be structured to maintain persistent state and execute sequential logic traditionally reserved for dedicated silicon CPUs.
While currently an experimental proof of concept, the methodology opens new avenues for edge computing and independent AI agents. The project documentation notes that the expanded resource usage nearly doubles the original model footprint to 19 gigabytes. Despite this memory overhead, the ability to run deterministic code inside a neural network represents a significant leap in how researchers conceptualize model architecture. Developers are now closely monitoring how this technique might evolve to optimize memory usage.
For more details on the open standard instruction set architecture enabling this breakthrough, you can review the official RISC-V International specifications. The fusion of neural inference and classical computing is no longer just a theoretical concept. It is actively running inside the weights of modern language models today.
Popular news
Nvidia Faces Severe Supply Constraints on Massive China GPU Orders
AI Chip Smugglers Exploit Trade Control Loophole To Bring Banned HBM Into China
AI Data Center Expansion Halted by Overwhelming Voter Rejection in Midterm Elections
Valve Updates Steam Release Rules Following AI Game Surge
DLSS 5 Is Changing How Your Games Look—Here’s How the AI Works