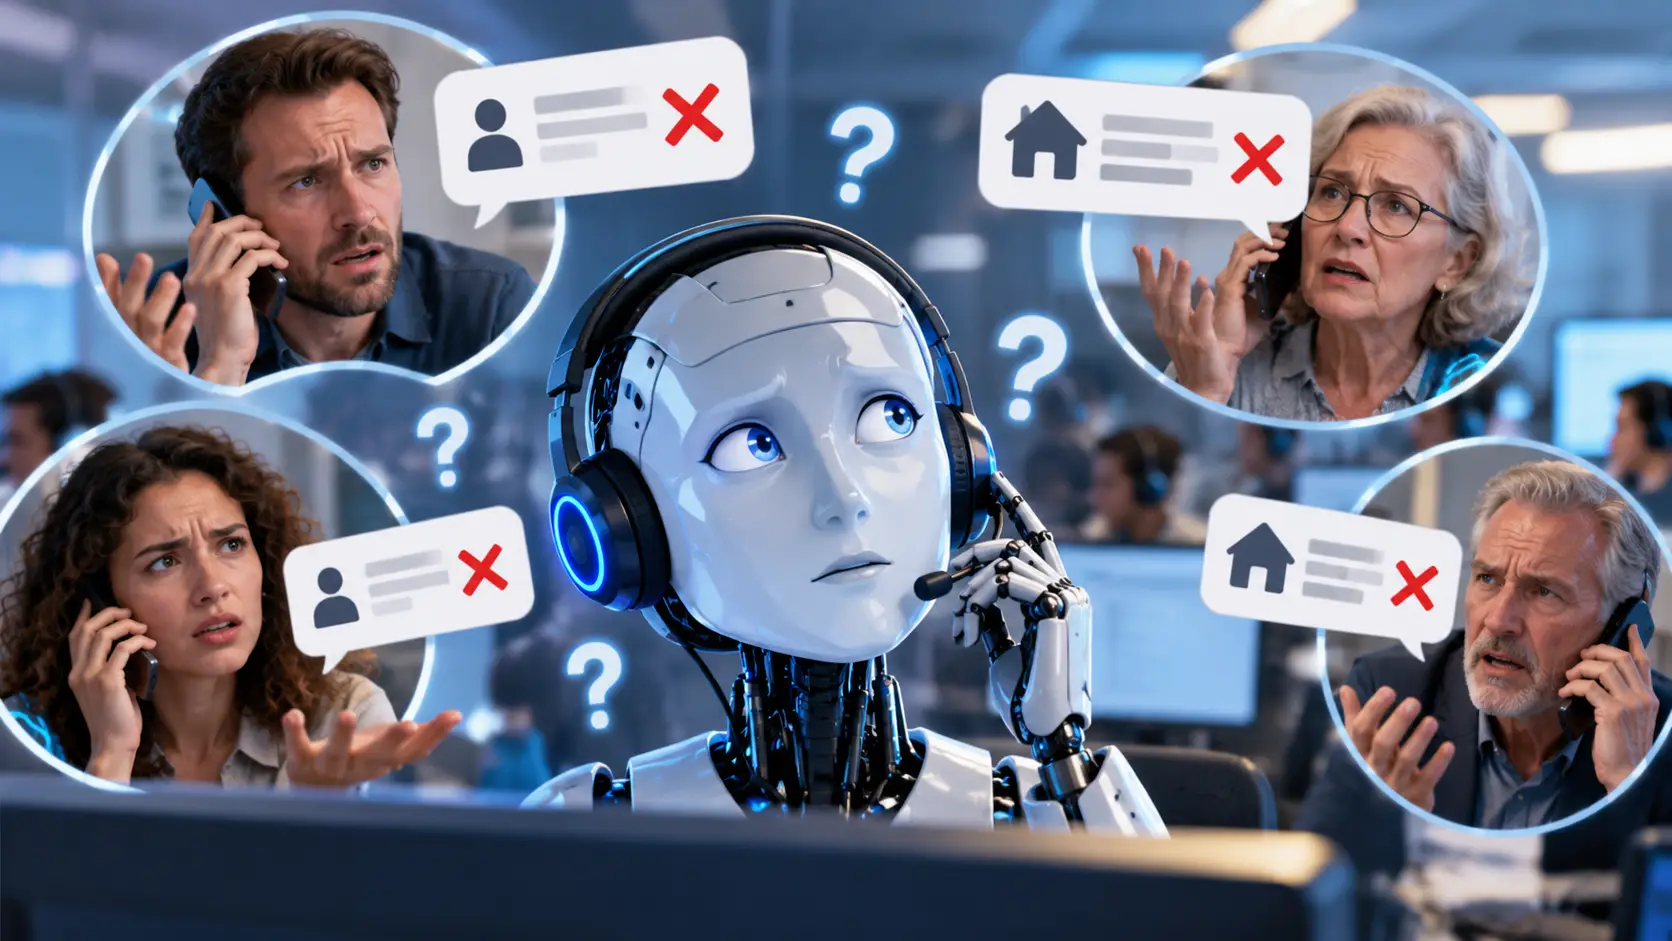
AI phone agents still struggle to reliably capture even basic personal information. That’s according to a study published by US AI company Sierra.
Researchers tested how accurately different voice assistants record names, phone numbers, addresses and other details during calls.
Even the top-performing system correctly handled the same information under three different conditions in just 34 percent of the tasks.
The findings from Sierra’s study show that a natural-sounding AI voice does not automatically make for a reliable phone agent.
Researchers put AI through 200 simple tasks
Sierra developed a test called τ-Entity, pronounced “tau-entity.”
It measures whether AI systems can accurately capture information people provide over the phone.
The test includes 200 tasks covering ten types of information, including names, email addresses, phone numbers and mailing addresses.
The tasks are deliberately kept relatively simple.
For example, an AI agent may be asked to request a missing detail and enter it correctly into a system.
The person on the other end cooperates and can spell out information when asked.
Researchers then repeat each task under three conditions: a regular conversation, a call with heavy background noise, and one with additional speech sounds.
The aim is not just to see whether AI gets it right once, but whether it can remain reliable as conditions change.
Top AI model gets it right in all conditions just 34% of the time
Sierra compared several voice models, including GPT Live 1, Gemini 3.8 Live and Grok Voice Think Fast 2.0.
GPT Live 1 achieved the highest score in the combined multilingual test.
In ordinary conditions, it correctly captured 60.3 percent of the requested information.
When the same task had to be completed successfully under all three conditions, the score fell to 34 percent.
Gemini 3.8 Live scored 43.8 percent in ordinary conditions and 19.5 percent across all three conditions.
Grok Voice Think Fast 2.0 scored 44.2 percent and 24 percent, respectively.
These figures need some context.
A score of 34 percent does not mean that the model fails in 66 percent of real customer calls. It reflects a specific controlled test in which details must be exact and the same task must be completed successfully under all three conditions.
The researchers also tested six languages, with results varying by language.
In English-only calls, for example, GPT Live 1 scored 74 percent under ordinary conditions.
The test highlights just how difficult it remains for AI to capture personal information accurately and consistently in changing conditions.
Mishearing a name can have serious consequences
In an everyday conversation, a misspelled name may seem like a minor issue.
In customer service, however, a mistake like that can have serious consequences.
Customers changing their address need to trust that the system records the correct street and house number.
Accuracy also matters when changing a phone number, checking a booking or providing an email address.
In some cases, an incorrectly recorded detail could prevent a customer from passing an identity check.
Sierra found that AI agents do not always recognize when they have misheard something.
Sometimes they ask the caller to confirm a detail, but still process the correction incorrectly.
The researchers also examined how systems behave when a call becomes more challenging.
That could mean a caller gives an unfamiliar name, corrects a mistake or calls from a noisy environment.
These situations are part of everyday life for real customer service teams.
AI Wereld previously covered research into how people in the Netherlands feel about AI customer service.
The new test adds a technical question: can an AI phone agent process information reliably enough to carry out tasks on behalf of an organization?
Extra confirmation improves accuracy—but makes calls longer
The researchers also explored how AI phone agents could reduce errors.
One possible solution is to give the assistant a standard verification process.
The AI first asks for the information, invites the caller to spell it out if needed, repeats it back and checks that it is correct.
According to Sierra, across the test setups, this raised reliability from 14–41 percent to 37–54 percent when measured across all three conditions.
The improvement varied by model and test setup.
The added checks came with a trade-off: calls took an average of 21 to 28 seconds longer.
That presents a significant choice for organizations.
A company may try to keep calls as short as possible to cut costs. But if AI mishandles personal information, correcting those mistakes could take far longer.
A separate test involving multiple details also showed how errors can compound. A system filling in three fields has more chances to get something wrong.
That matters for Dutch companies, even though Sierra did not test Dutch separately.
The findings show that the quality of AI phone service depends on more than a pleasant voice or quick answers.
A reliable AI phone agent must be able to listen carefully, recognize uncertainty and actually correct its mistakes.
For tasks involving personal information or payments, that reliability appears at least as important as handling the call quickly.
Loading